October 2, 2016
Systemd is not Magic Security Dust
Systemd maintainer David Strauss has published a response to my blog post about systemd. The first part of his post is replete with ad hominem fallacies, strawmen, and factual errors. Ironically, in the same breath that he attacks me for not understanding the issues around threads and umasks, he betrays an ignorance of how the very project which he works on uses threads and umasks. This doesn't deserve a response beyond what I've called out on Twitter.
In the second part of his blog post, Strauss argues that systemd improves security by making it easy to apply hardening techniques to the network services which he calls the "keepers of data attackers want." According to Strauss, I'm "fighting one of the most powerful tools we have to harden the front lines against the real attacks we see every day." Although systemd does make it easy to restrict the privileges of services, Strauss vastly overstates the value of these features.
The best systemd can offer is whole application sandboxing. You can start a daemon as a non-root user, in a restricted filesystem namespace, with mandatory access control. Sandboxing an entire application is an effective way to run potentially malicious code, since it protects other applications from the malicious one. This makes sandboxing useful on smartphones, which need to run many different untrustworthy, single-user applications. However, since sandboxing a whole application cannot protect one part of the application from a compromise of a different part, it is ineffective at securing benign-but-insecure software, which is the problem faced on servers. Server applications need to service requests from many different users. If one user is malicious and exploits a vulnerability in the application, whole application sandboxing doesn't protect the other users of the service.
For concrete examples, let's consider Apache and Samba, two daemons which Strauss says would benefit from systemd's features.
First Apache. You can start Apache as a non-root user provided someone else binds to ports 443 and 80. You can further sandbox it by preventing it from accessing parts of the filesystem it doesn't need to access. However, no matter how much you try to sandbox Apache, a typical setup is going to need a broad amount of access to do its job, including read permission to your entire website (including password-protected parts) and access to any credential (database password, API key, etc.) used by your CGI, PHP, or similar webapps.
Even under systemd's most restrictive sandboxing, an attacker who gains remote code execution in Apache would be able to read your entire website, alter responses to your visitors, steal your HTTPS private keys, and gain access to your database and any API consumed by your webapps. For most people, this would be the worst possible compromise, and systemd can do nothing to stop it. Systemd's sandboxing would prevent the attacker from gaining access to the rest of your system (absent a vulnerability in the kernel or systemd), but in today's world of single-purpose VMs and containers, that protection is increasingly irrelevant. The attacker probably only wants your database anyways.
To provide a meaningful improvement to security without rewriting in a memory-safe language, Apache would need to implement proper privilege separation. Privilege separation means using multiple processes internally, each running with different privileges and responsible for different tasks, so that a compromise while performing one task can't lead to the compromise of the rest of the application. For instance, the process that accepts HTTP connections could pass the request to a sandboxed process for parsing, and then pass the parsed request along to yet another process which is responsible for serving files and executing webapps. Privilege separation has been used effectively by OpenSSH, Postfix, qmail, Dovecot, and over a dozen daemons in OpenBSD. (Plus a couple of my own: titus and rdiscd.) However, privilege separation requires careful design to determine where to draw the privilege boundaries and how to interface between them. It's not something which an external tool such as systemd can provide. (Note: Apache already implements privilege separation that allows it to process requests as a non-root user, but it is too coarse-grained to stop the attacks described here.)
Next Samba, which is a curious choice of example by Strauss. Having configured Samba and professionally administered Windows networks, I know that Samba cannot run without full root privilege. The reason why Samba needs privilege is not because it binds to privileged ports, but because, as a file server, it needs the ability to assume the identity of any user so it can read and write that user's files. One could imagine a different design of Samba in which all files are owned by the same unprivileged user, and Samba maintains a database to track the real ownership of each file. This would allow Samba to run without privilege, but it wouldn't necessarily be more secure than the current design, since it would mean that a post-authentication vulnerability would yield access to everyone's files, not just those of the authenticated user. (Note: I'm not sure if Samba is able to contain a post-authentication vulnerability, but it theoretically could. It absolutely could not if it ran as a single user under systemd's sandboxing.)
Other daemons are similar. A mail server needs access to all users' mailboxes. If the mail server is written in C, and doesn't use privilege separation, sandboxing it with systemd won't stop an attacker with remote code execution from reading every user's mailbox. I could continue with other daemons, but I think I've made my point: systemd is not magic pixie dust that can be sprinkled on insecure server applications to make them secure. For protecting the "data attackers want," systemd is far from a "powerful" tool. I wouldn't be opposed to using a library or standalone tool to sandbox daemons as a last line of defense, but the amount of security it provides is not worth the baggage of running systemd as PID 1.
Achieving meaningful improvement in software security won't be as easy as adding a few lines to a systemd config file. It will require new approaches, new tools, new languages. Jon Evans sums it up eloquently:
... as an industry, let's at least set a trajectory. Let's move towards writing system code in better languages, first of all -- this should improve security and speed. Let's move towards formal specifications and verification of mission-critical code.
Systemd is not part of this trajectory. Systemd is more of the same old, same old, but with vastly more code and complexity, an illusion of security features, and, most troubling, lock-in. (Strauss dismisses my lock-in concerns by dishonestly claiming that applications aren't encouraged to use their non-standard DBUS API for DNS resolution. Systemd's own documentation says "Usage of this API is generally recommended to clients." And while systemd doesn't preclude alternative implementations, systemd's specifications are not developed through a vendor-neutral process like the IETF, so there is no guarantee that other implementers would have an equal seat at the table.) I have faith that the Linux ecosystem can correct its trajectory. Let's start now, and stop following systemd down the primrose path.
September 28, 2016
How to Crash Systemd in One Tweet
The following command, when run as any user, will crash systemd:
NOTIFY_SOCKET=/run/systemd/notify systemd-notify ""
After running this command, PID 1 is hung in the pause system call.
You can no longer start and stop daemons. inetd-style services no longer
accept connections. You cannot cleanly reboot the system. The system
feels generally unstable (e.g. ssh and su hang for 30 seconds since
systemd is now integrated with the login system). All of this can be
caused by a command that's short enough to fit in a Tweet.
Edit (2016-09-28 21:34): Some people can only reproduce if they wrap the command in a while true loop. Yay non-determinism!
The bug is remarkably banal. The above systemd-notify command sends a
zero-length message to the world-accessible UNIX domain socket located
at /run/systemd/notify. PID 1 receives the message and
fails
an assertion that the message length is greater than zero.
Despite the banality, the bug is serious, as it allows any local user
to trivially perform a denial-of-service attack against a critical
system component.
The immediate question raised by this bug is what kind of quality assurance process would allow such a simple bug to exist for over two years (it was introduced in systemd 209). Isn't the empty string an obvious test case? One would hope that PID 1, the most important userspace process, would have better quality assurance than this. Unfortunately, it seems that crashes of PID 1 are not unusual, as a quick glance through the systemd commit log reveals commit messages such as:
- coredump: turn off coredump collection only when PID 1 crashes, not when journald crashes
- coredump: make sure to handle crashes of PID 1 and journald special
- coredump: turn off coredump collection entirely after journald or PID 1 crashed
Systemd's problems run far deeper than this one bug. Systemd is defective by design. Writing bug-free software is extremely difficult. Even good programmers would inevitably introduce bugs into a project of the scale and complexity of systemd. However, good programmers recognize the difficulty of writing bug-free software and understand the importance of designing software in a way that minimizes the likelihood of bugs or at least reduces their impact. The systemd developers understand none of this, opting to cram an enormous amount of unnecessary complexity into PID 1, which runs as root and is written in a memory-unsafe language.
Some degree of complexity is to be expected, as systemd provides a number of useful and compelling features (although they did not invent them; they were just the first to aggressively market them). Whether or not systemd has made the right trade-off between features and complexity is a matter of debate. What is not debatable is that systemd's complexity does not belong in PID 1. As Rich Felker explained, the only job of PID 1 is to execute the real init system and reap zombies. Furthermore, the real init system, even when running as a non-PID 1 process, should be structured in a modular way such that a failure in one of the riskier components does not bring down the more critical components. For instance, a failure in the daemon management code should not prevent the system from being cleanly rebooted.
In particular, any code that accepts messages from untrustworthy sources like systemd-notify should run in a dedicated process as a unprivileged user. The unprivileged process parses and validates messages before passing them along to the privileged process. This is called privilege separation and has been a best practice in security-aware software for over a decade. Systemd, by contrast, does text parsing on messages from untrusted sources, in C, running as root in PID 1. If you think systemd doesn't need privilege separation because it only parses messages from local users, keep in mind that in the Internet era, local attacks tend to acquire remote vectors. Consider Shellshock, or the presentation at this year's systemd conference which is titled "Talking to systemd from a Web Browser."
Systemd's "we don't make mistakes" attitude towards security can
be seen in other places, such as
this code from the main() function of PID 1:
/* Disable the umask logic */
if (getpid() == 1)
        umask(0);
Setting a umask of 0 means that, by default, any file created by systemd
will be world-readable and -writable. Systemd defines a macro called RUN_WITH_UMASK
which is used to temporarily set a more restrictive umask when systemd needs to create a file
with different permissions. This is backwards. The default umask should be restrictive,
so forgetting to change the umask when creating a file would result in a file
that obviously doesn't work. This is called fail-safe design. Instead systemd is fail-open, so forgetting to change the umask
(which
has already happened twice) creates a file that works but is a potential security vulnerability.
The Linux ecosystem has fallen behind other operating systems in writing secure and robust software. While Microsoft was hardening Windows and Apple was developing iOS, open source software became complacent. However, I see improvement on the horizon. Heartbleed and Shellshock were wake-up calls that have led to increased scrutiny of open source software. Go and Rust are compelling, safe languages for writing the type of systems software that has traditionally been written in C. Systemd is dangerous not only because it is introducing hundreds of thousands of lines of complex C code without any regard to longstanding security practices like privilege separation or fail-safe design, but because it is setting itself up to be irreplaceable. Systemd is far more than an init system: it is becoming a secondary operating system kernel, providing a log server, a device manager, a container manager, a login manager, a DHCP client, a DNS resolver, and an NTP client. These services are largely interdependent and provide non-standard interfaces for other applications to use. This makes any one component of systemd hard to replace, which will prevent more secure alternatives from gaining adoption in the future.
Consider systemd's DNS resolver. DNS is a complicated, security-sensitive protocol. In August 2014, Lennart Poettering declared that "systemd-resolved is now a pretty complete caching DNS and LLMNR stub resolver." In reality, systemd-resolved failed to implement any of the documented best practices to protect against DNS cache poisoning. It was vulnerable to Dan Kaminsky's cache poisoning attack which was fixed in every other DNS server during a massive coordinated response in 2008 (and which had been fixed in djbdns in 1999). Although systemd doesn't force you to use systemd-resolved, it exposes a non-standard interface over DBUS which they encourage applications to use instead of the standard DNS protocol over port 53. If applications follow this recommendation, it will become impossible to replace systemd-resolved with a more secure DNS resolver, unless that DNS resolver opts to emulate systemd's non-standard DBUS API.
It is not too late to stop this. Although almost every Linux distribution now uses systemd for their init system, init was a soft target for systemd because the systems they replaced were so bad. That's not true for the other services which systemd is trying to replace such as network management, DNS, and NTP. Systemd offers very few compelling features over existing implementations, but does carry a large amount of risk. If you're a system administrator, resist the replacement of existing services and hold out for replacements that are more secure. If you're an application developer, do not use systemd's non-standard interfaces. There will be better alternatives in the future that are more secure than what we have now. But adopting them will only be possible if systemd has not destroyed the modularity and standards-compliance that make innovation possible.
February 5, 2016
Domain Validation Vulnerability in Symantec Certificate Authority
Symantec was disregarding + and = characters
in email addresses when parsing WHOIS records, allowing certificate
misissuance for domains whose WHOIS contacts contained these characters.
The vulnerability has been reported and fixed. Read on for more...
There are three common ways for the requester of a domain-validated SSL certificate to prove control over the domain in the certificate request: add a record to the domain's DNS, publish a file on the domain's website, or respond to an email sent to an administrative address at the domain. The basic idea is that getting a DV certificate should require doing something that only the domain administrator can do. Adding a DNS record is the best way to ensure this: it's unlikely that anyone but the administrator could add records to a domain's DNS. Publishing a file on the domain's website is pretty good too, although some websites accept user uploads in a way that might be abused.
Email validation, on the other hand, is the worst way. Besides being impossible to automate, it's certainly the easiest to abuse. One problem is that the person receiving an email at an "administrative" address might not actually be an administrator. This is a big problem for email service providers who allow users to register arbitrary email addresses at their domains. In 2008, Mike Zusman was able to register the email address sslcertificates@live.com and use it to approve an SSL certificate for live.com. Back then, certificate authorities allowed you to choose from quite a large list of possible administrative addresses, which compounded the problem. Now, the Baseline Requirements (the rules governing public certificate issuance) define the administrative addresses as admin@, administrator@, hostmaster@, postmaster@, and webmaster@, which helps but is not a panacea: just last year, an unnamed Finn was able to register hostmaster@live.fi and use it to obtain a certificate for live.fi.
The Baseline Requirements also allow email addresses from the domain's WHOIS record to be used for certificate approval. These addresses don't suffer from the problem above: the WHOIS record is controlled by the domain's registrant, who wouldn't list an email address if it didn't belong to an administrator of the domain. Unfortunately, there's a pretty major implementation pitfall awaiting those who use WHOIS: WHOIS records are not machine-readable. They are unstructured, human-readable text. Even worse, every TLD uses its own format!
How does one take an unstructured, human-readable document, and extract
some bit of information such as an email address from it in realtime?
I suspect that most solutions are going to involve a regular
expression that matches a sequence of characters that look like an email address. What
constitutes a valid email address? The answer may surprise you. The relevant standard,
RFC 5322,
allows a shocking assortment of characters to appear in the local part (the part
to the left of the at sign) of an email address, including, but not limited to, +, =, !, #, {, `, and ^.
If you escape or quote the local part, you can even include control characters, although
the madness of permitting control characters is considered obsolete.
If a certificate authority does not properly consider the full range of characters when
parsing a WHOIS record, they risk extracting the wrong email address for a domain, allowing
an unauthorized party to obtain certificates for it. Last October, I discovered that Symantec's DV certificate
products (RapidSSL, QuickSSL) did not consider + and = characters when parsing WHOIS
records. If an email address in WHOIS contained either character, Symantec would treat
the part of the address following the character as a valid administrative address. For example,
if a domain's WHOIS contact was this:
andrew+whois@gmail.com
then Symantec would allow the following address to approve certificates for the domain:
whois@gmail.com
This was a serious flaw. + is commonly used in email addresses for
sub-addressing,
which permits person+anything@example.com to be used as an alias for
person@example.com. Several popular email service providers, including
Gmail, Outlook.com, and Fastmail support sub-addressing with the plus
character, and I know from my experience running SSLMate that it is not
uncommon for domain administrators to use an email address such as
person+whois@gmail.com for their WHOIS contact. An attacker could register
whois@gmail.com and fraudulently obtain certificates from Symantec for
any domain whose WHOIS contact followed this pattern.
As a proof of concept, I set all three WHOIS email addresses of a test domain, cloudpork.com, to alice+bob@cloudpork.com:
$ whois cloudpork.com | grep Email Registrant Email: ALICE+BOB@CLOUDPORK.COM Admin Email: ALICE+BOB@CLOUDPORK.COM Tech Email: ALICE+BOB@CLOUDPORK.COM Registrar Abuse Contact Email: abuse@enom.comI then went to RapidSSL to obtain a DV certificate for www.cloudpork.com, and was presented with the following choice of email addresses:
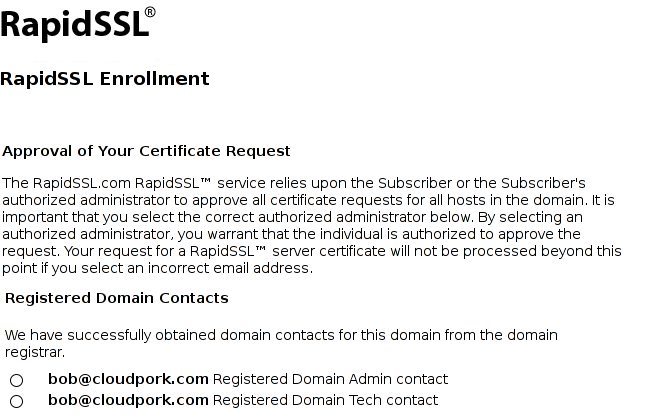
I selected bob@cloudpork.com, received the approval email at that address, and after approving the certificate was issued a valid SSL certificate for www.cloudpork.com, despite bob@cloudpork.com not being a valid administrative address for cloudpork.com.
I reported the vulnerability to Symantec on October 21, 2015. I also reported it to the four major trust store operators (Google, Mozilla, Microsoft, and Apple), which I believe is appropriate for vulnerabilities in publicly-trusted certificate authorities. Symantec reported that the issue was fixed on October 28, which I confirmed. Symantec then conducted a rather lengthy audit of previously-issued certificates to ensure that this vulnerability had not been exploited. The vulnerability was publicly disclosed yesterday.
In the end, I was able to confirm that Symantec properly handled +, =, -, _, and . characters in email addresses.
I wish I could have tested with additional non-alphanumeric characters, but I couldn't find a domain registrar who would let me
include such characters in WHOIS. Fortunately, the likelihood of someone
using a special character besides +, =, -, _, or . in their domain's WHOIS contact is pretty low.
Furthermore, email providers tend not to allow such bizarre characters in email addresses, so if someone
were to use such an email address, it would most likely be hosted at their own domain, where the risk
of the email being misdirected to an unauthorized person would be low.
I'm glad this vulnerability is fixed, but it serves as a reminder that the certificate authority system still has much room for improvement. I have high hopes for Certificate Transparency, a system which would require certificate authorities to log all certificates they issue to public, append-only, and auditable logs (browsers would enforce this by only accepting a certificate if it was accompanied by cryptographic proof of the certificate's inclusion in a log). Domain owners could monitor these logs for certificates related to their domain, so if a vulnerability such as this one were exploited to misissue certificates, it would be detected. The Certificate Transparency experiment is already underway: many certificates have been logged, and can be searched using the awesome crt.sh tool from Comodo. I'm working on some of my own tools to help domain owners use Certificate Transparency; stay tuned!
December 2, 2015
Duplicate Signature Key Selection Attack in Let's Encrypt
Cryptography is notorious for its sharp edges. It's easy to make a minor mistake that totally dooms your security. The situation is improving thanks to the development of easier-to-use libraries like libsodium which provide a high-level interface instead of forcing the user to combine basic building blocks. However, you still need to know exactly what security guarantees your cryptographic primitives provide and be sure not to go beyond their guarantees.
As an example of what can go wrong when you assume too much from a primitive, consider the duplicate signature key selection attack which I discovered in ACME, the protocol used by Let's Encrypt. The vulnerability was severe and would have allowed attackers to obtain SSL certificates for domains they didn't control. Fortunately, it was mitigated before Let's Encrypt was publicly trusted, and was definitively fixed a couple weeks ago.
The vulnerability was caused by a misuse of digital signatures. The guarantee provided by digital signatures is the following:
Given a message, a signature, and a public key, a valid digital signature tells you that the message was authored by the holder of the corresponding private key.
This guarantee is handy for many use cases, such as verifying that an email is authentic. If you receive a signed email that claims to be from Bob, you can use Bob's public key to verify the signature. If an attacker, Mallory, alters the email, the signature is no longer valid. It is computationally infeasible for Mallory to compute a valid signature since she doesn't know Bob's private key.
What if Mallory could trick you into using her public key, not Bob's, to verify the message? Clearly, this would doom security. After altering the email, Mallory could replace Bob's signature with a signature from her own private key. When you verify it with Mallory's public key, the message will appear authentic.
But what if Mallory were able to alter the message and trick you into using her public key, but she was not able to replace the signature, perhaps because it was delivered out-of-band? The obvious attack, re-signing the message with her private key, won't work. So is this system secure? Is Mallory stymied?
No. Mallory just needs to find a private key which produces the same signature for her altered message as Bob's private key produced for his original message, and nothing says this can't be done. Digital signatures guarantee that a message came from a particular private key. They do not guarantee that a signature came from a particular private key, and with RSA it's quite easy to find a private key that produces a desired signature for a particular message. This means that a signature does not uniquely identify a message, which is interesting because it's easy to naively think of signatures as "hashes with public key crypto" but in this way they are very unlike hashes. Similarly, a signature alone does not identify a key, which makes digital signatures unlike handwritten signatures, which (theoretically) uniquely identify a person.
A system that gets this wrong may be vulnerable to a duplicate signature key selection attack. Let's see how this works with RSA.
Brief recap of RSA
RSA signatures work using exponentiation modulo an integer. RSA public keys consist of the modulus n (typically a 2048 bit integer that is the product of two random primes) and the public exponent e (typically 65537). Private keys consist of the same modulus n, plus the private exponent d, such that (xd)e = x (mod n) for all x. It's easy to calculate d from e if you know the prime factorization of n, which only the person who generated the key pair should know. Without this information, calculating d is considered infeasible.
To sign a message m, you raise it to the power of d (mod n) to produce the signature s:
| s | = | md | (mod n) |
To verify a message, you take the signature, raise it to the power of e (mod n), and compare it against the message:
| se | ≟ | m | (mod n) |
Since s = md, and (xd)e = x (mod n) for all x, raising s to the power of e should produce m, as long as neither the message nor the signature were altered.
Note that m has to be just the right length, so you never sign the message itself. Instead you sign a cryptographic hash of the message that has been padded using a padding scheme such as PKCS#1 v1.5 or PSS. This detail doesn't matter for understanding the attack so I will henceforth assume that the message to be signed has already been hashed and padded.
Crafting an RSA key
In a duplicate signature key selection attack, the signature s is fixed. The attacker gets to choose the message m, and then has to construct an RSA key under which s is a valid signature for m. In other words, find e, d, and n such that:
| se | = | m | (mod n) |
and:
| (xd)e | = | x | (mod n) | for all x |
There's a trivial solution which is silly but works with some RSA implementations. Just set e = 1, d = 1, and n = s - m. Clearly, the second equation is satisfied. It's not hard to see that the first equation is satisfied too:
| s | = | m | (mod s - m) |
| s - m | = | 0 | (mod s - m) |
| 0 | = | 0 | (mod s - m) |
This requires m < s, but since the first byte of PKCS#1 v1.5 padding is always zero, m < s will be true with high probability if you use PKCS#1 v1.5 padding (note that the choice of padding is controlled by the attacker; it doesn't matter what padding the victim's signature uses).
This produces a highly implausible RSA key pair. e and d are 1, which means that signing doesn't do anything, and the modulus n is less than the signature s, which shouldn't happen with modular arithmetic. However, not all RSA implementations are picky with these details. For example, Go's RSA implementation happily validates such signatures (Let's Encrypt's backend is written in Go). Note that this is in not a bug in Go, since these details don't matter when signatures are used properly.
There is a more sophisticated way to pick the RSA key that produces a valid key pair that would be accepted by all RSA implementations. Finding e such that se = m (mod n) is an instance of the discrete logarithm problem. Whether or not the discrete logarithm problem is difficult depends on n, which the attacker gets to choose. The attacker can choose n such that it's easy to find the corresponding e and d. Although the resulting key pair will look slightly odd to the human eye (since e is conventionally 3 or 65537), it will be a perfectly valid key pair. For more details about this technique, see page 4 of this paper by Koblitz and Menezes.
Attacking ACME
ACME is a protocol for the automated issuance of SSL certificates. It was developed for and is used by Let's Encrypt, and is currently undergoing standardization at the IETF. In ACME, messages from the client are signed using the client's ACME account key, which is typically an RSA or ECDSA key. When an ACME client asks the server to issue a certificate for a particular domain, the server replies with one or more "challenges" which the client must complete successfully to prove that it controls that domain.
One of the challenges is the DNS challenge. In an earlier draft of ACME, the client signed a "validation object" with its ACME account key, published the signature in a TXT record under the domain, and then sent the validation object and signature to the ACME server. The server would verify the signature using the client's account key and then query the TXT record. If the signature was valid, and the value of the TXT record matched the signature, the challenge would succeed. Since only the administrator of a domain can create DNS records, it was presumed that this challenge was secure.
As we saw above, such a scheme is vulnerable to a duplicate signature key selection attack. A digital signature does not uniquely identify a key or a message. So if Mallory wants to obtain a certificate for Bob's domain, she doesn't need to alter Bob's DNS records if Bob has already published his own signature in the DNS. Mallory just needs to choose her ACME account key so that her validation object has the same signature as Bob's. When Mallory sends her validation object to the ACME server, the server will query Bob's TXT record, see that Bob's signature matches the signature of Mallory's validation object, and conclude incorrectly that Mallory put the signature in Bob's DNS, and is therefore authorized to obtain certificates for Bob's domain.
For a more in-depth description of my attack, see my report to the IETF ACME list.
Resolution
Shortly after I reported the vulnerability to the IETF ACME mailing list on August 11, 2015, Let's Encrypt mitigated the attack by removing the ability to start a challenge with one account key and finish it with a different one, which deprived the attacker of the ability to pick an account key that would produce the right signature for the validation object. Since Let's Encrypt was not yet publicly trusted, at no point was the integrity of the public certificate authority system at risk from this attack. Still, the underlying misuse of signatures remained, so ACME has been redesigned so that a hash of the ACME account public key (plus a random token) is published in the DNS instead of a signature. The old challenges were disabled on November 19, 2015.
Edited (2015-12-04): Remove incorrect mention of modular inverses from my recap of RSA. Thanks to Reader Sam Edwards for pointing out my error.
October 8, 2015
I Don't Accept the Risk of SHA-1
Website operators have to configure a dizzying number of security properties for their website: protocol versions, TLS ciphers, certificate hash algorithm, and so on. Most of these properties provide an individual benefit: when you configure your server to require secure protocol versions and strong ciphers, connections to your website are immediately made more secure. It doesn't affect your website's security if some other schmuck is still using SSLv3 with RC4 and 1024 bit Diffie-Hellman on their website.
However, other security properties, particularly those related to certificates, provide more of a collective security benefit, where everyone's security is determined by the security of the lowest common denominator. A timely example is the hash algorithm used in certificate signatures. Until recently, SHA-1 was the most common algorithm. Unfortunately, SHA-1 is dangerously weak so the Internet is transitioning to the more secure SHA-2. Under the current deprecation schedule, certificate authorities must stop issuing SHA-1 certificates on January 1, 2016, and SHA-1 certificates that are issued before then must not be valid past January 1, 2017, which means that on January 1, 2017, browsers can stop trusting SHA-1 certificates.
Unfortunately, since this is a collective security property, there's nothing an individual website operator can do in the meantime to improve the security of their site. This site, www.agwa.name, uses a SHA-2 certificate, but the truth is that it's no more secure than a site using a SHA-1 certificate. That's because an attacker who can generate a SHA-1 collision can forge a SHA-1 certificate for www.agwa.name. Since so many websites still use SHA-1 certificates, and it's not 2017 yet, web browsers will accept the forged certificate and be none the wiser. None of us will be more secure until certificate authorities stop signing, and web browsers stop accepting, certificates with SHA-1 signatures.
For this reason, I was dismayed by the recent proposal from Symantec to allow certificate authorities to issue SHA-1 certificates through the end of 2016, because some of their "very large enterprise customers" can't complete the migration in time. Although their proposal would not change the date on which browsers would stop trusting SHA-1, it would extend the period during which new collisions could be created. This was troubling enough when the proposal was made last week, and is even more troubling in light of the research released today that estimates the cost of finding a SHA-1 collision on EC2 to be between just $75,000 and $120,000.
What made me really angry about the proposal was the following statement:
These customers accept the risk of continuing to use new SHA-1 certificates
"These customers" accept the risk? As I explained above, the use of SHA-1 is a collective risk shared by the entire Internet, not just the "very large enterprise customers" who want to keep using SHA-1. What about the rest of the Internet, who want their TLS connections to be secure and who have dutifully migrated to SHA-2 in time for the deadline? Did anyone ask them? I sure as hell don't accept the risk.
The statement is therefore vacuous and thoroughly unpersuasive to anyone who understands how certificates work. But to someone who doesn't understand or isn't reading too closely, it makes the proposal seem less bad for the Internet at large than it really is. I hope that the other members of the CA/Browser Forum see through this and reject the proposal.